DeepSeek V4.1 Flash
DeepSeek V4.1 Flash is a multimodal coding, reasoning and agent model first released on September 10, 2026 and updated to V4.1-Flash-1017 on October 17. DeepSeek says its website, app and API now serve 1017. Use `deepseek-flash` for the current hosted version; the API still supports 1M context, up to 384K output and image input. The dated 1017 weights are public under MIT.
The October update improves DeepSeek's reported coding and agent results without changing its direct API ID or token prices. Existing integrations receive a newer model behind the same name, so regression-test accepted tasks rather than assuming a stable ID pins behavior. The September architecture and retirement of the older hosted Flash models remain separate historical changes.
The October 17 announcement and model card describe a minor update with stronger vendor-reported results and shorter task execution and outputs. The current direct API documentation preserves the price and access contract. Published demonstrations show selected coding projects, while early community discussions raise questions about harness choice, reasoning-token use and repeatability; neither proves a universal quality or cost winner.
- Run low-cost long-context coding and agent workflows through the DeepSeek API.
- Analyze screenshots, charts, documents, and other supported images alongside text.
- Connect Responses- or Anthropic-compatible agent clients to one multimodal endpoint.
- Evaluate an MIT-licensed open model on suitably provisioned inference infrastructure.
- Migrate from the retired V4 Flash and Vision Exp endpoints with explicit regression checks.
Use `deepseek-flash` for the current hosted model. DeepSeek retired the original V4 Flash and V4 Flash Vision Exp models; their IDs remain accepted only as temporary compatibility aliases to V4.1 Flash. That means a successful request under an old name no longer reproduces the old model.
- DeepSeek
The company operating the hosted API and publishing the model weights and research.
- Current hosted ID: `deepseek-flash`.
- Legacy aliases: `deepseek-v4-flash` and `deepseek-v4-flash-vision-exp`.
- Current dated checkpoint: `deepseek-ai/DeepSeek-V4.1-Flash-1017` under the MIT License.
- September checkpoint: `deepseek-ai/DeepSeek-V4.1-Flash`; this is distinct from the rolling hosted ID.
DeepSeek describes a 552B-parameter backbone using a Causal Encoder-Decoder architecture. Prefill activates about 8B parameters per input token and decode activates about 16B per output token. The company says the design uses one quarter of the previous generation's HBM for KV cache and one eighth of its SSD storage. These are architectural and vendor-measured claims, not proof of the same savings in every serving stack.
The hosted API lists 1M context, 384K maximum output, image understanding, thinking and non-thinking modes, JSON output, tool calls, Responses, Anthropic-compatible Messages, prefix completion beta, and FIM in non-thinking mode. Off peak, one million tokens cost $0.003 for cache-hit input, $0.15 for cache-miss input, and $0.60 for output; peak rates are double. Peak hours are 01:00–04:00 and 06:00–10:00 UTC on weekdays excluding Chinese public holidays. The October 17 update keeps these prices unchanged.
The model card publishes weights, a technical report, and serving guidance, but the checkpoint is still very large. DeepSeek's own deployment note invites clusters on the order of thousands of GPUs for large-scale service. Quantization and hybrid loading can change the hardware boundary, but local anecdotes should report exact format, hardware, speed, context, and quality rather than calling the model laptop-friendly.
The September 10 launch reports results across science, mathematics, coding, cybersecurity, agents, vision and tool use. Those scores describe the original V4.1 checkpoint. Keep them separate from the October update and compare the same benchmark version, tools, effort and acceptance checks before replacing a working model.
Hacker News and Reddit interest is unusually strong. Readers focus on the old-ID redirect, actual parameter accounting, local serving feasibility, output speed, reasoning-token use, and whether a cheaper model finishes a whole coding task. Those are useful evaluation questions; individual screenshots and one-off runs remain anecdotal.
DeepSeek calls 1017 a minor update and attributes the complete-project improvements to reinforcement learning with self-feedback. Its model card compares the dated checkpoint with September V4.1 Flash. These are DeepSeek-reported results, not independent GetLLMs evaluations.
- October 17 release and demonstrations
DeepSeek's selected project examples and release explanation.
- 1017 model card and weights
The dated checkpoint, MIT license and benchmark conditions.
- HLE without tools: 36.8 to 42.6; the separate text-only-subset scores are 39.1 to 44.0.
- Terminal-Bench 4.0: 31.2 to 42.3, using Claude Code. DeepSWE v1.1: 74.2 to 77.0, using Mini-SWE-V2.
- The reported runtime and output-length reductions do not establish a fixed speedup or task cost for every workload.
- DeepSeek recommends Harness v0.2.1-rc.1 or later. The hosted API ID rolls forward; use the dated checkpoint when you need an identifiable open-weight version.
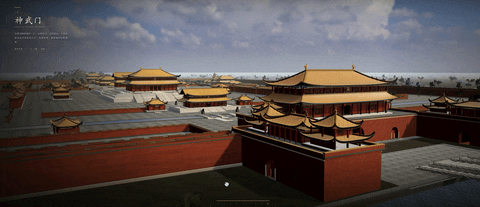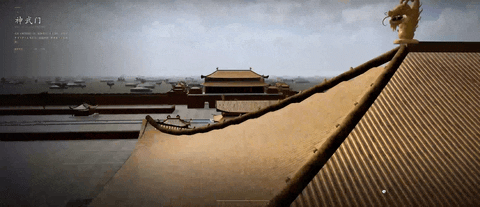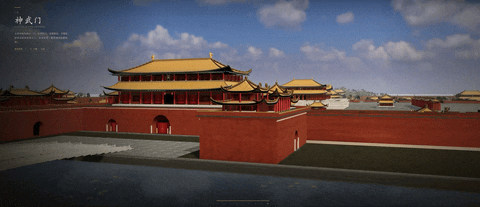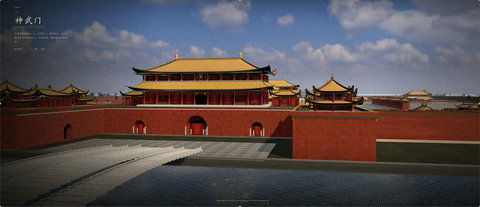
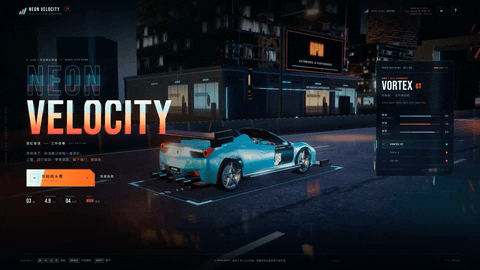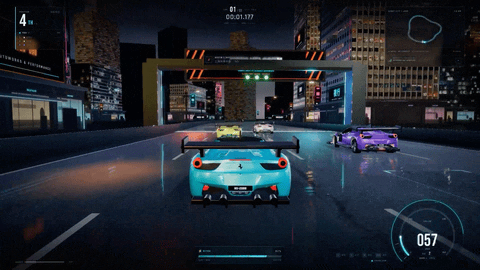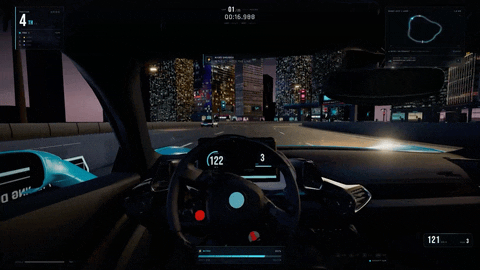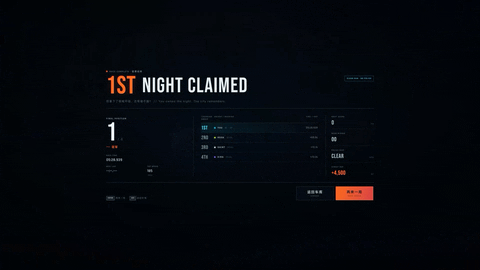
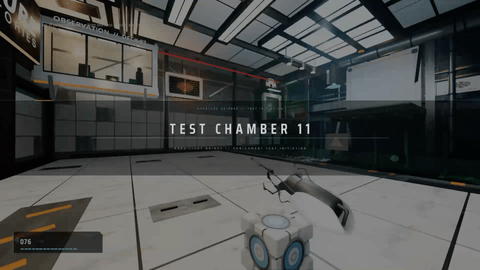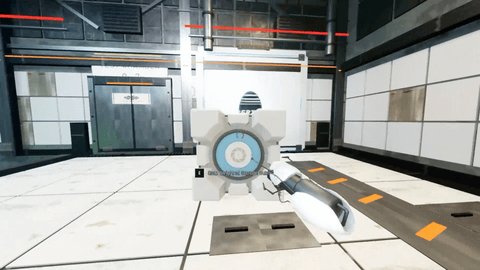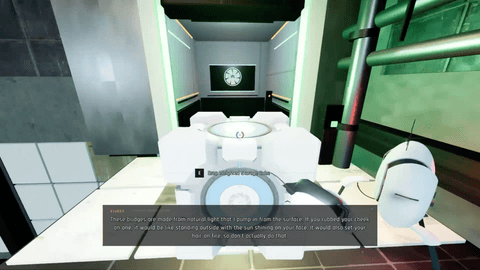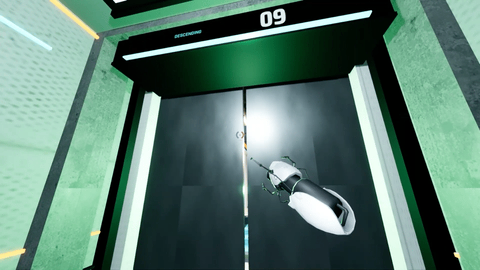
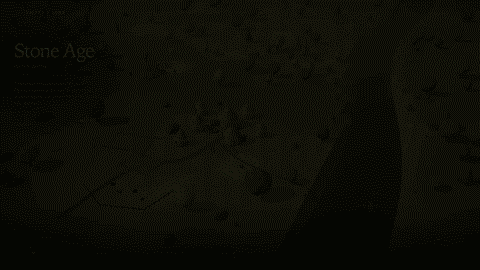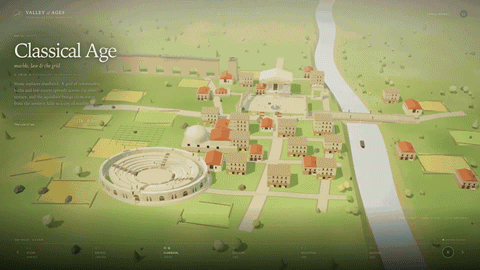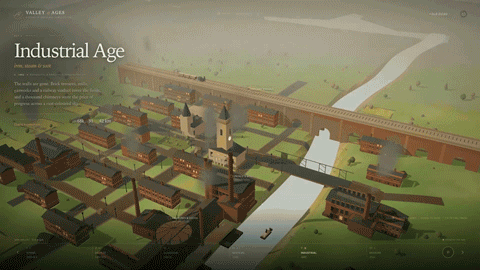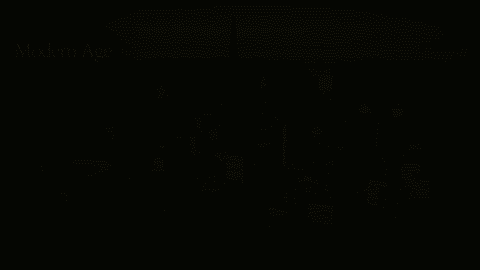
DeepSeek's October 17 announcement shows four short recordings of projects built through coding workflows: a Forbidden City model, a browser racing game, a Godot Portal2 recreation and Valley of Ages. The examples used prompts, reference materials and interactions in DeepSeek Harness. They are selected publisher demonstrations, not native video generation, independent evaluations or a guarantee that the same project completes in one request. Open each original animation below or read the release for context.
- Forbidden City: 3D modeling demonstration
DeepSeek's original recording of a generated architectural scene.
- Browser racing game demonstration
DeepSeek's original recording of a game project running in a browser.
- Godot Portal2 recreation demonstration
DeepSeek's original recording of a project built with the Godot engine.
- Valley of Ages: 3D scene demonstration
DeepSeek's original recording of a scene depicting changes across historical eras.
DeepSeek also opened standalone web Search and Fetch APIs on October 17. They retrieve pages and Markdown for agents; they are separate from model inference. Each costs $0.75 per 1,000 successful requests. Server-side calls through DeepSeek Harness, Claude Code or Codex are temporarily free for DeepSeek API users, with billing starting November 1, 2026 at 00:00 Beijing time. Do not assume that exemption covers direct standalone API calls.
- Search and Fetch usage and billing
Official endpoints, response formats, billable success conditions and rate limits.
DeepInfer’s default offline example uses the V4.1-Flash-1017 checkpoint. The public repository documents optimized kernels and execution on NVIDIA SM100/Huawei Ascend 950, but still requires additional cache, disaggregation and replica load-balancing work for a complete service. This is not evidence of a changed hosted API contract or a laptop-ready deployment.
- DeepInfer
Read the public engine’s scope and prerequisites.
The company operating the hosted API and publishing the model weights and research.
The retired 0731 predecessor and legacy API alias.
The retired experimental vision predecessor and legacy alias.
The Pro endpoint whose current routing notices conflict across official pages.
Source confidence
DeepSeek API Docs
DeepSeek API Docs
DeepSeek on Hugging Face
DeepSeek API Docs
DeepSeek API Docs
DeepSeek API Docs
DeepSeek on Hugging Face
Hacker News
Reddit r/DeepSeek
DeepSeek
DeepSeek V4.1 Flash FAQ
Common questions about DeepSeek V4.1 Flash.
What is the API model ID for DeepSeek V4.1 Flash?+
Use `deepseek-flash`; DeepSeek says it serves V4.1-Flash-1017 after the October 17 update. The older `deepseek-v4-flash` and `deepseek-v4-flash-vision-exp` names are temporary compatibility aliases, not a way to pin the previous models.
Does DeepSeek V4.1 Flash accept images?+
Yes. DeepSeek documents native image understanding alongside text input and text output. Verify the supported content-block format in the active API and client adapter.
Can I run DeepSeek V4.1 Flash locally?+
The weights are MIT-licensed and public, but the model is large. Local feasibility depends on quantization, memory, storage, context target, serving runtime, and acceptable speed; a successful small-hardware demo does not establish production throughput.
Is V4.1 Flash the same as the old V4 Flash?+
No. It uses a new architecture, adds native image input, has a different open checkpoint and price schedule, and replaces the older hosted Flash models. Legacy IDs route to it only for compatibility.
Is V4.1 Flash better than V4 Pro?+
DeepSeek says it outperforms V4 Pro across performance, cost, speed, and total time, but that is a provider claim. Official pages also conflict about the current V4 Pro route, so compare observed endpoints on your own accepted tasks.
Do I need a new API model name or pay more for 1017?+
No. DeepSeek says the October 17 upgrade keeps the `deepseek-flash` API name, calling method and token prices unchanged. The dated Hugging Face checkpoint is a separate download identity; Search and Fetch have their own request-based charges.